Видео с ютуба Efficient Inference

What is vLLM? Efficient AI Inference for Large Language Models

AI Inference: The Secret to AI's Superpowers

Mastering LLM Inference Optimization From Theory to Cost Effective Deployment: Mark Moyou
Faster LLMs: Accelerate Inference with Speculative Decoding
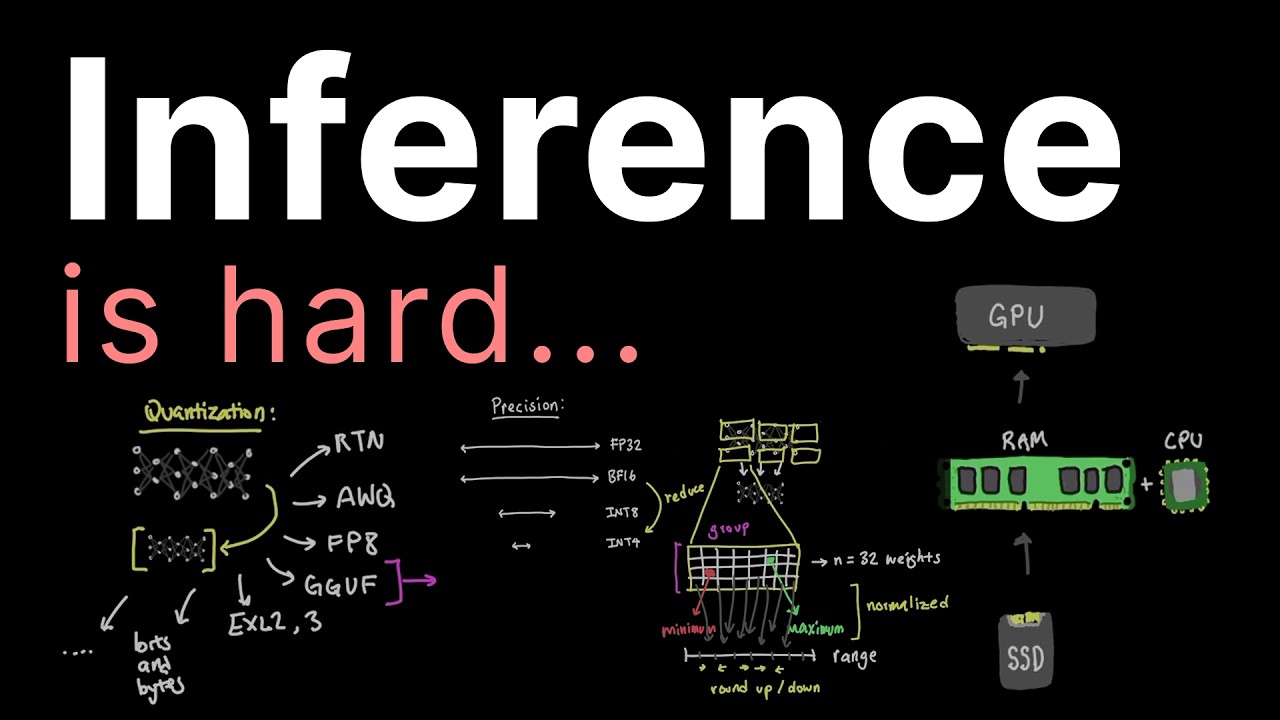
Почему делать логические выводы сложно...
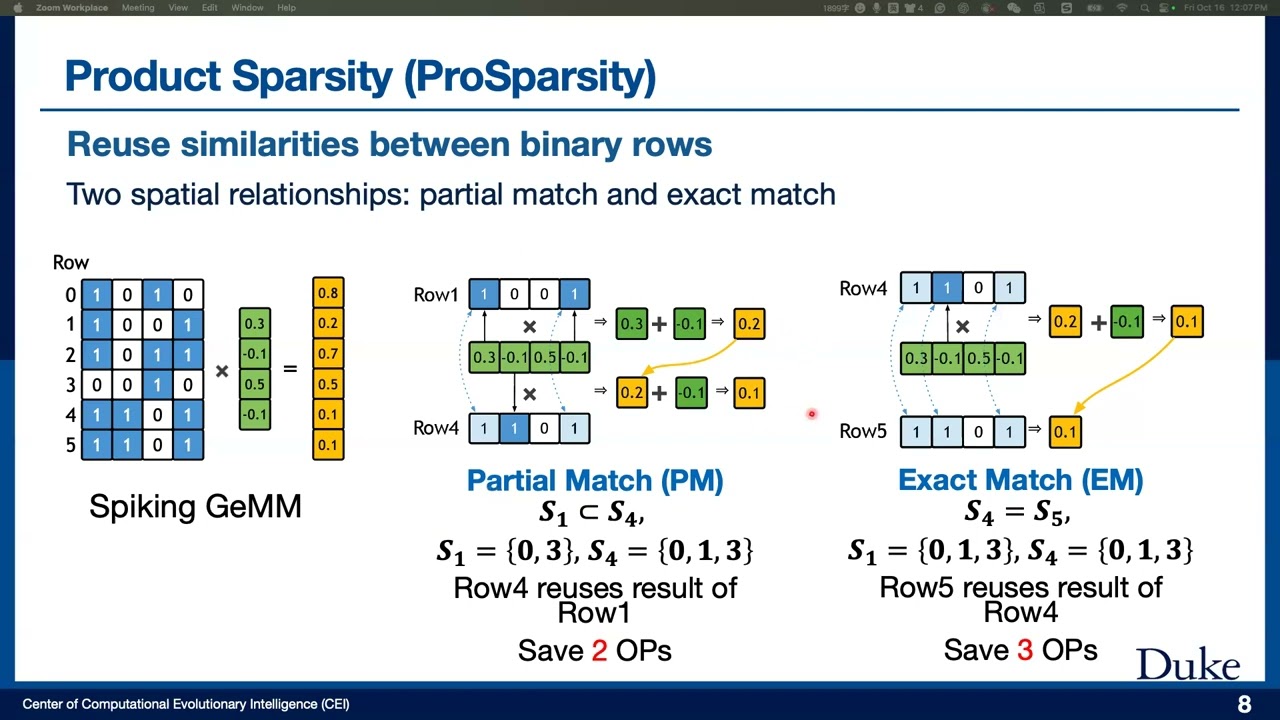
Beyond Zero-Skipping: Redundancy-Aware Architectures and Systems for Efficient AI Inference
Быстрый и эффективный инференс в масштабе на гетерогенном оборудовании | Gimlet Labs x d-Matrix |...
The secret to cost-efficient AI inference

Deep Dive: Optimizing LLM inference
Европа создала Jotunn 8 — самый энергоэффективный в мире чип для ИИ-инференса | Стоит ли NVIDIA в...

Lightning Talk: Efficient Inference at the Edge: Performance You Need at the Lowest... - Felix Baum

8. The Path Toward Energy-Efficient Inference Engine Architectures on Scaled and Beyond-CMOS Fabrics

Спонсируемая сессия: Lightning Talk: Эффективное обслуживание выводов с помощью Kubernetes Gatewa...
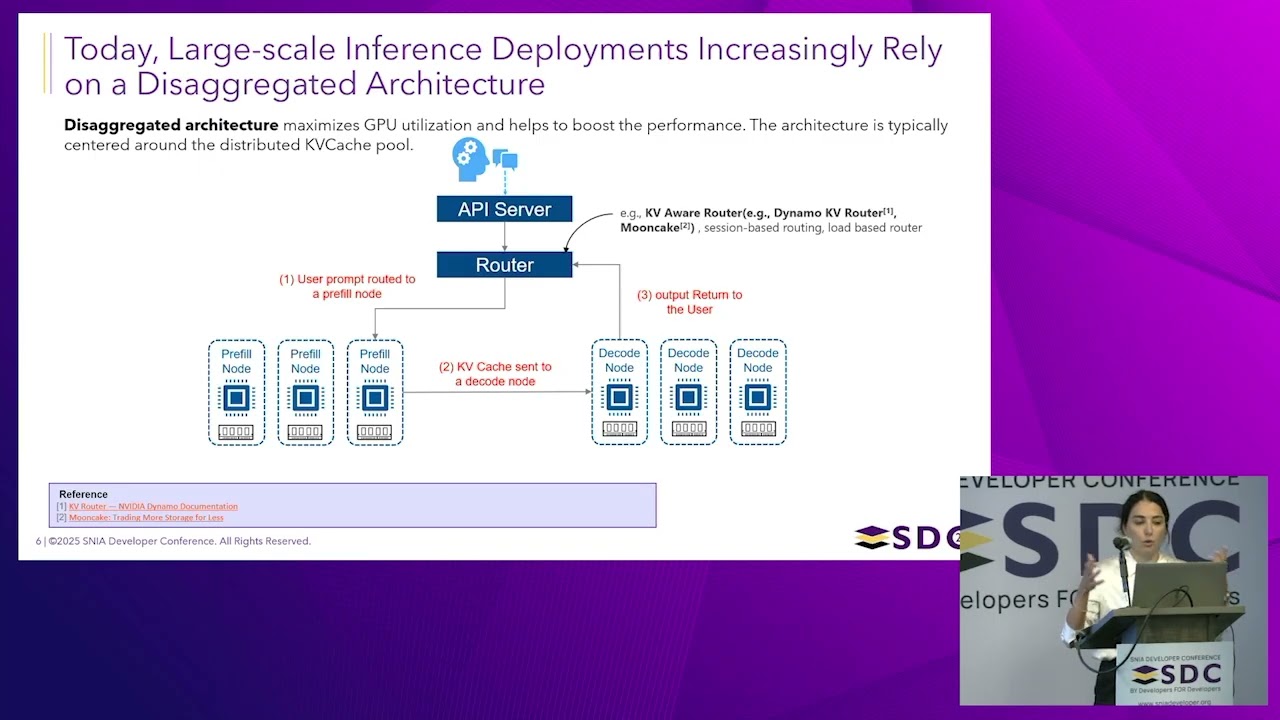
SNIA SDC 2025 — Разгрузка хранилища KV-кэша для эффективного вывода в LLM
AI Chips, Token Efficiency & the Future of Inference Infrastructure | Joo-Young Kim - AIS5

Fast & Efficient LLM Inference with vLLM-S01 Introduction
Лекция 13: Эффективный вывод LLM

#OCPSummit26: Efficient AI Inference at Rack Scale

Hidden Markov Model: Parameter Estimation & Efficient Inference